
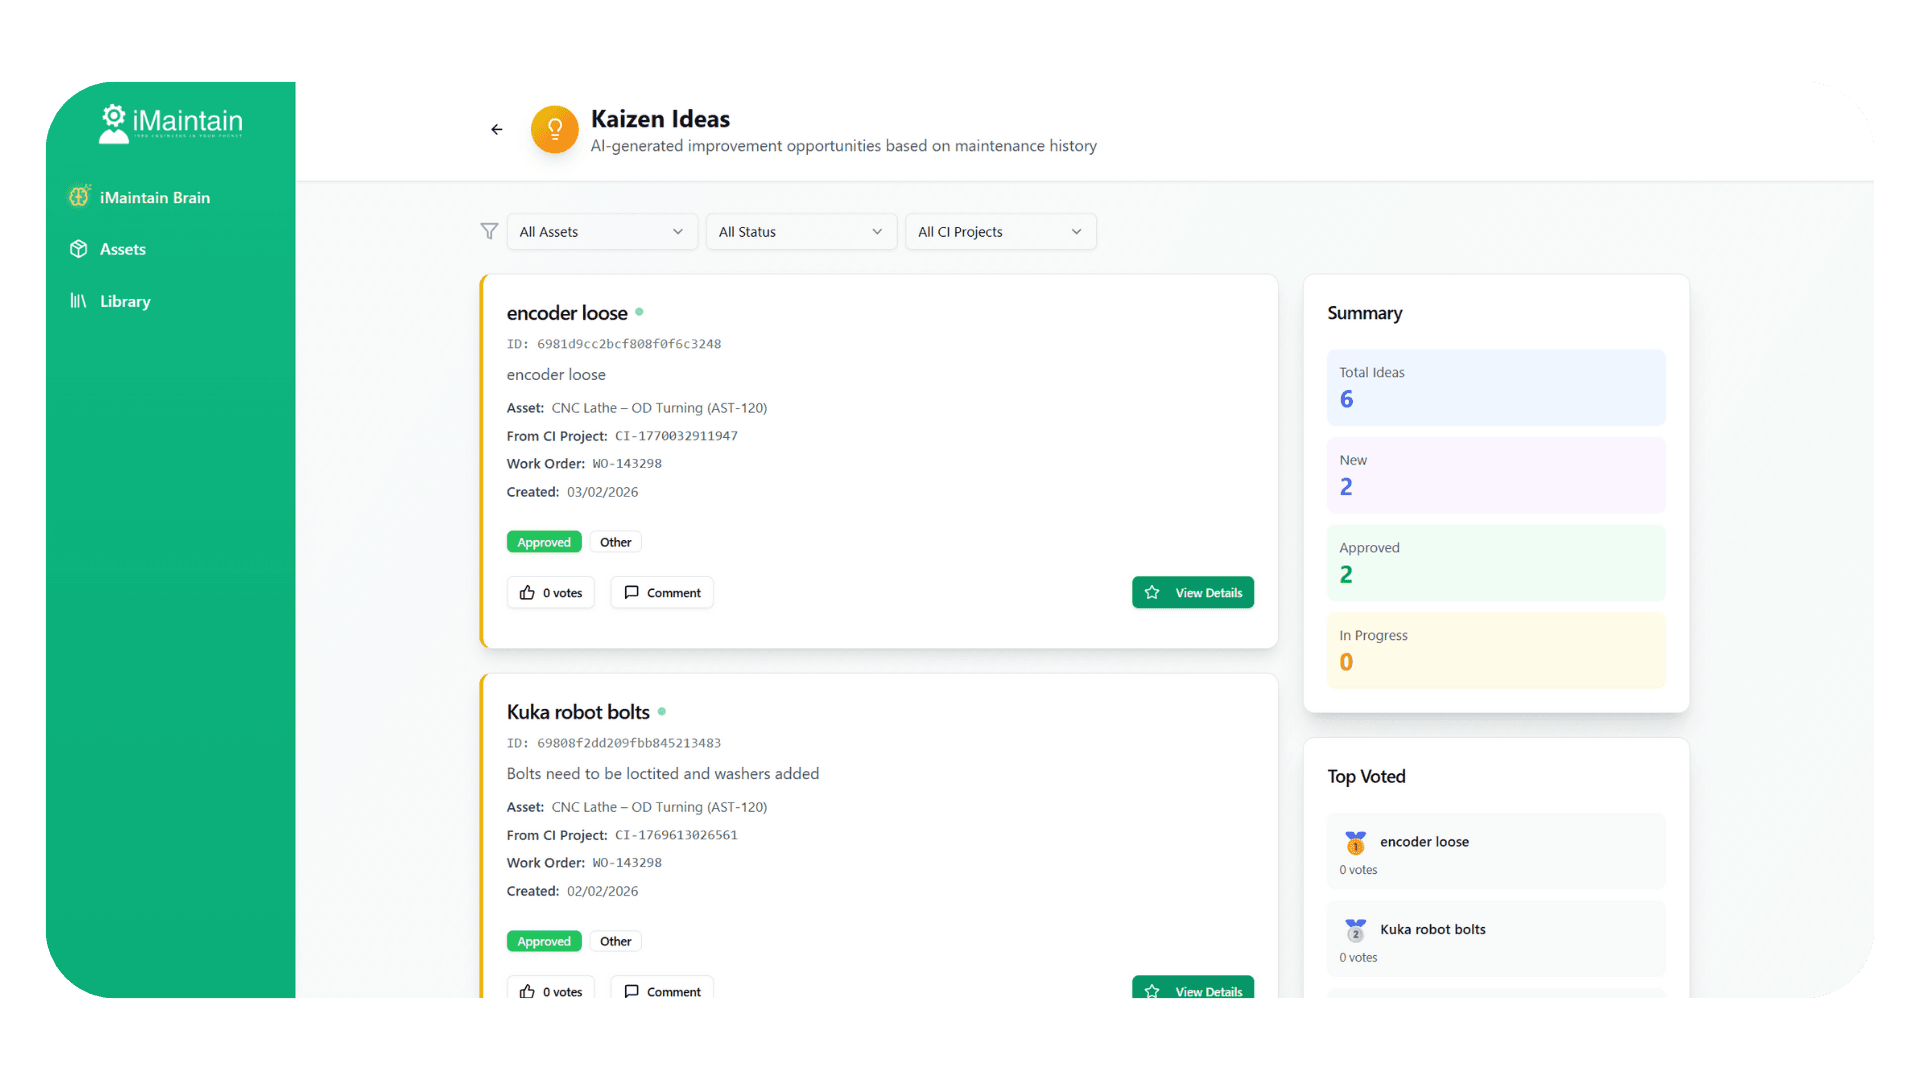
Moving from reactive to preventive maintenance requires shifting your team from constant firefighting to structured, condition-based intervention before machinery breaks down. By combining real-time equipment data with AI-driven insights from past work orders, maintenance teams can anticipate critical component failures, reduce Mean Time to Repair (MTTR), and eliminate recurring factory line stops.
Most maintenance teams spend their shifts chasing broken belts, blown valves, and overheated gearboxes. They want a cleaner schedule, but production pressure always gets in the way. Shifting your strategy does not require millions in brand-new machinery or ripping out the systems your technicians already use. Instead, it starts with making sense of the operational data you already log every day.
The Reality of Moving from Reactive to Preventive Maintenance
Every plant manager wants reliable machines. Yet walking the factory floor reveals a familiar story: alarms sounding, grease guns flying, and technicians rushing between breakdowns. Moving from reactive to preventive maintenance is the single highest-impact operational change a factory can make, but traditional attempts often stumble because they simply flood engineers with arbitrary calendar-based tasks that do not prevent unexpected failures.
When you introduce artificial intelligence and predictive analytics into this workflow, the equation fundamentally changes. Rather than blindly swapping parts every six weeks regardless of condition, engineering teams can use historical maintenance context, asset documentation, and operational data to pinpoint failure modes before they halt production. To make this shift practical on the shop floor, maintenance leaders use dedicated intelligence platforms. Explore iMaintain RMP to see how a Reliability Management Platform can connect maintenance data, technical information, and engineer knowledge to support better reliability decisions.
Why Are Factories Stuck in the Reactive Maintenance Trap?
It feels like an endless loop. A machine trips, the operator calls the shift engineer, the engineer fixes the symptom as fast as possible to get the line rolling, and the real underlying cause gets ignored. Why does this happen?
- Production pressure: Operators need parts out the door. Taking a machine offline for two hours of deep inspection feels impossible when dispatch deadlines loom.
- Fragmented maintenance logs: Your computerised maintenance management system holds ten years of history, but nobody has time to search through thousands of records during an active breakdown.
- Tribal knowledge: Dave knows the eccentric quirk of packaging machine four. If Dave is on leave or retires, that critical troubleshooting know-how walks straight out the factory gates.
- Admin overload: Engineers spend more time fighting clunky forms on desktop computers than fixing root causes, leading to one-line work orders like “fixed sensor” or “cleared jam”.
When your team lives in reactive mode, the business pays a silent, compounding tax. You pay through rush freight on replacement components, lost production hours, rushed shift handovers, and burnt-out maintenance engineers.
What Is the Difference Between Reactive, Preventive, and Predictive Maintenance?
To build a better maintenance strategy, we have to clear up the industry terms. People throw around “preventive” and “predictive” as if they are the exact same thing, but they address equipment health differently.
Reactive Maintenance (Run-to-Failure)
You run the machine until something snaps, burns, or stalls. This strategy makes sense for cheap, non-critical assets like office lightbulbs, but using it on a critical bottling line or packaging cell is catastrophic. It leads to maximum disruption, high emergency shipping costs, and severe safety hazards.
Preventive Maintenance (Calendar-Based)
You inspect, lubricate, or replace parts based on fixed operating hours or elapsed calendar days. For instance, changing the oil on a compressor every 90 days. While far better than reactive firefighting, calendar preventive maintenance has blind spots: you often replace perfectly good components, or worse, miss sudden wear caused by variable production speeds or harsh environments.
Predictive and AI-Driven Reliability
Predictive maintenance relies on condition indicators (such as vibration, motor load, operating temperatures) coupled with intelligent history analysis to flag anomalies. Instead of guessing when a bearing will fail, machine learning models and smart analytics track subtle deviations. When paired with frontline troubleshooting context, engineers can fix the root issue before an unplanned line stop strikes.
How Predictive Analytics Transforms Everyday Shop-Floor Decisions
What does predictive analytics actually look like on a noisy factory floor? It is not about fancy dashboards hidden in a manager’s office. It is about giving frontline technicians clear, actionable insight right when they stand in front of a broken machine.
- Early Pattern Detection: Bearings rarely seize instantly. They generate tiny harmonic vibrations and micro-temperature increases weeks before catastrophic seizure. Analytics tools capture these tiny drifts.
- Contextual History Retrieval: When a line trips on a motor overload fault, an intelligent system immediately pulls up every time that specific motor tripped over the last two years, highlighting what previously cured the problem.
- Root Cause Analysis (RCA): Instead of replacing a burnt proximity switch five times in a row, analytics helps reliability engineers realise that a loose mounting bracket is vibrating the sensor out of alignment.
- Work Order Prioritisation: AI algorithms score maintenance requests based on asset criticality and repeat-failure trends, ensuring technicians tackle the high-risk issues first.
5 Steps to Transition from Reactive Firefighting to Structured Reliability
Shifting your maintenance culture does not require an overnight revolution. It requires five steady, practical steps.
Step 1: Clean Your Asset Hierarchy and Categorise Criticality
You cannot protect every motor in the building simultaneously. Start by ranking your assets using an ABC criticality model:
- Tier A Assets: Bottle-neck machines. If these stop, the entire factory halts and you lose thousands of pounds per minute.
- Tier B Assets: Important machines with local buffers or parallel redundancies.
- Tier C Assets: Non-critical equipment that can safely wait for scheduled downtime.
Focus all your early analytical energy and reliability efforts exclusively on Tier A assets.
Step 2: Stop Losing Engineer Knowledge
Your most valuable reliability asset is not a sensor; it is the collective experience of your engineering team. When an experienced engineer solves a difficult intermittent electrical fault, that resolution must be captured immediately without saddling them with twenty minutes of paperwork. Modern tools turn quick voice notes or short frontline summaries into structured, searchable records.
Step 3: Spot and Target Repeat Faults
Look closely at your recent work orders. You will almost certainly find that twenty percent of your machines cause eighty percent of your downtime calls. Treat repeat failures as systemic warnings rather than isolated bad luck. If your team had instant access to previous fixes when an alarm sounds, MTTR drops sharply. Download our ‘When The Line Stops’ Guide for practical advice on finding the right maintenance information faster when time is against you.
Step 4: Layer AI on Top of Existing Systems
Many manufacturing executives think that getting modern reliability insight requires replacing their existing CMMS. That is a myth. Ripping out enterprise software is painful, expensive, and alienates technicians. The modern answer is to add a dedicated reliability layer that reads your existing CMMS history, manuals, and schematics, turning static records into live troubleshooting assistance.
Step 5: Implement Smoother Shift Handovers
How many recurring problems fester because the morning shift engineer forgets to tell the evening shift about an ongoing hydraulic pressure drop? Structured handovers compiled from completed jobs ensure continuous visibility. When shifts communicate through objective data, hidden equipment degradation gets resolved before it causes an emergency stop.
Why Traditional CMMS Tools Fall Short for Frontline Troubleshooting
Most manufacturing facilities already own a Computerised Maintenance Management System (CMMS) or Enterprise Asset Management (EAM) tool. These platforms are vital systems of record. They excel at logging purchase orders, managing spare part inventories, and ticking off compliance tasks.
However, standard CMMS platforms were built for maintenance auditing, not frontline diagnostic speed. When an engineer stands beside a stalled packaging line with production managers breathing down their neck, they cannot waste fifteen minutes running nested SQL queries or clicking through dropdown menus to find out what cured this fault six months ago. As a result, engineers guess, swap random parts, or call someone who might remember.
This is where a Reliability Management Platform (RMP) enters the picture. It does not replace the CMMS; it sits beside it. The CMMS keeps managing compliance and inventory, while the RMP gives engineers immediate answers, surfaces repeat faults, and feeds clean data straight back into the system of record.
If you want to keep your existing software but help your engineering team work smarter, see how iMaintain works with your CMMS to bridge the gap between historical logs and real-time troubleshooting.
Proven Results from Frontline Engineering Leaders
Manufacturing leaders across industries are already proving that practical, AI-driven reliability tools deliver rapid returns without system disruption.
“iMaintain is far superior to other systems we’ve seen on the market. What really sets it apart is the way it uses AI to assist engineers and support root cause analysis.”
— Chris Cole, Maintenance Manager, The Senator Group“The product sells itself and the price point sits easy in anyone’s maintenance budget.”
— Chris Cole, Maintenance Manager, The Senator Group“I am excited to see how iMaintain can help our technicians get the information they need faster, support us in root cause analysis, and also help improve our PM’s by recognising trends in repeat failures.”
— James Hunter, Head of Engineering, Senstronics
Practical Troubleshooting: How Engineers Save Hours on the Line
Imagine an automated filling machine starts throwing intermittent servo error codes on line three. Under a traditional reactive regime:
- The operator calls the engineer.
- The engineer resets the drive. It runs for ten minutes, then trips again.
- The engineer swaps out the servo drive, suspecting internal electronics failure. Downtime: ninety minutes.
- Two hours later, the fault reoccurs. The real cause was a fraying cable bundle inside the flex track.
Now, imagine the same scenario with an AI reliability layer:
- The engineer types the servo error code into iMaintain RMP.
- The system scans the machine’s full history, OEM manuals, and previous fixes across the site.
- It instantly flags: “Three occurrences in the past 14 months on Line 3. On two occasions, resetting the drive failed; the root cause was mechanical wire fatigue inside the upper drag chain.”
- The technician inspects the harness immediately, finds the damaged wire, solders or replaces the section, and gets production rolling in fifteen minutes.
That is the difference between blindly guessing and relying on structured, institutional intelligence.
Overcoming Culture Challenges: Getting Technicians on Board
Engineers are naturally sceptical of new technology. If management rolls out a tool that smells like “monitoring software” or adds five extra forms to every repair, technicians will resist it. To succeed in shifting from reactive to preventive maintenance, you must respect the engineer’s daily reality.
- Demonstrate instant utility: The tool must help them solve tough problems faster. If it saves them from getting shouted at during a bad shift, they will adopt it.
- Reduce keyboard typing: Use conversational queries, auto-fill capabilities, and smartphone-friendly inputs. Maintenance technicians are craftspeople, not office data-entry clerks.
- Celebrate root cause fixes: Reward technicians who find and eliminate the cause of a repeat headache, rather than only celebrating the person who heroically fixes a dramatic midnight breakdown.
Frequently Asked Questions About Maintenance Transformation
How long does it take to move from reactive to preventive maintenance?
Most manufacturing plants see noticeable reductions in MTTR within two to three months of capturing structured maintenance data and surfacing repeat faults. Achieving a mature, predictive reliability programme across an entire facility generally takes six to twelve months of consistent implementation.
Do we have to replace our existing CMMS to use AI predictive tools?
No. Modern Reliability Management Platforms like iMaintain RMP are built to work alongside your existing CMMS or EAM. Your CMMS remains the system of record for compliance, assets, and work orders, while the AI layer provides diagnostic speed, knowledge retention, and repeat fault analysis.
What if our existing maintenance history data is poor quality?
This is normal. Most factories have short, vague work order notes like “cleared jam” or “reset drive”. Dedicated reliability platforms solve this by using AI to structure your historical documents, operating manuals, and electrical schematics first, while prompting technicians for better, low-effort context on new jobs going forward.
Will predictive analytics eliminate the need for skilled technicians?
Never. AI does not possess mechanical touch, craftsmanship, or safety judgement. The goal of predictive analytics and reliability platforms is to strip away administrative friction, highlight patterns that humans cannot spot in massive databases, and give engineers the precise technical context they need to make rapid, expert decisions.
How does this approach reduce our spare parts inventory costs?
When you run a reactive maintenance shop, you hoard expensive spare parts out of fear because you never know what will break next. By analysing asset trends and moving to predictive condition monitoring, you can order components just in time, reducing tied-up working capital and preventing spare parts from gathering dust on warehouse shelves.
Stop Guessing and Build a Resilient Reliability Strategy
Chasing breakdowns burns out your engineering staff, drains your operational budget, and leaves your plant vulnerable to devastating downtime. You do not need to replace your entire digital infrastructure or buy expensive new machinery to take control of your maintenance outcomes. By bridging your maintenance history, technical manuals, and team experience, you can systematically turn reactive chaos into calm, predictable performance.
Ready to see what your existing maintenance data can actually do? Book a demo to explore how iMaintain RMP can transform your troubleshooting, eliminate repeat faults, and protect your plant uptime.